

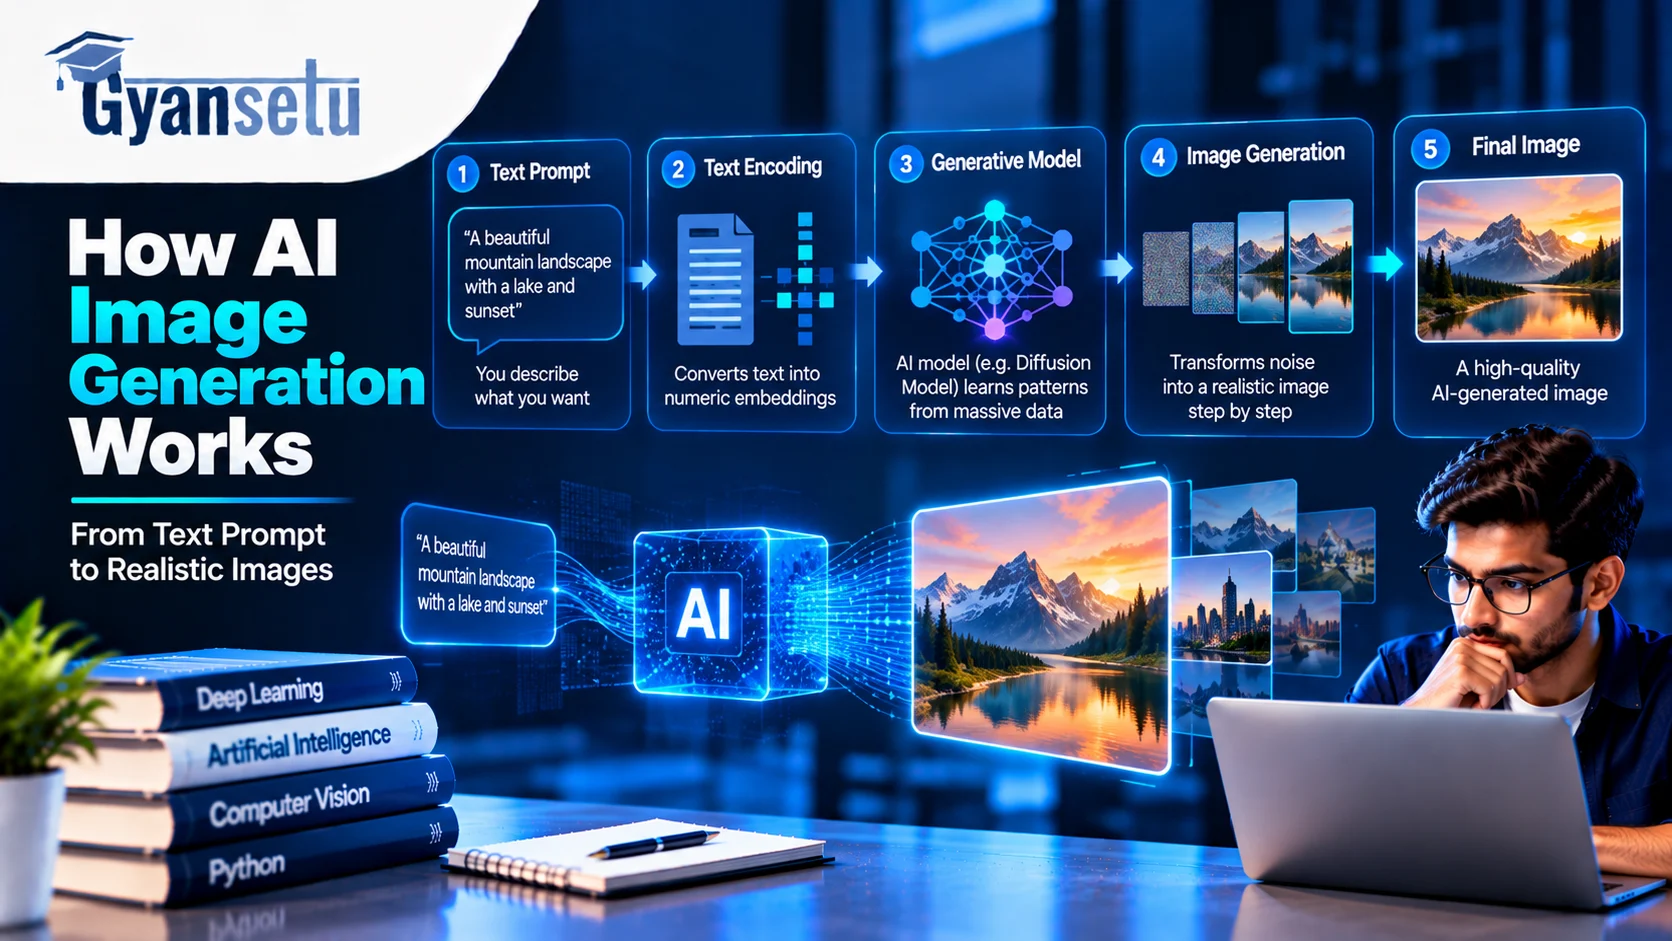
Type a sentence into an AI image generator, and seconds later, you have an image which never existed before.
So what really happened in between?
The simple explanation is this: the model translates your instructions into numerical encodings, which it then uses to steer a generative model based on these encodings, and gradually builds up an image from a learned representation of visual patterns.
For most modern AI image generators, the intuitive way to understand what’s going on is through diffusion: Start from nothing, keep refining, and try to guide the process by the prompt. Yet contemporary image generators are not all built in the exact same way. Some use diffusion transformers, some other methods, and even a combination of both. The important thing is to grasp the basic principles behind the interface.
What Will I Learn?
Quick answer: How does AI image generation work?
A typical AI image generation pipeline can be summarized by:
Prompt → Text representation → Conditioning → Initial noisy or image representation → Generation step-by-step → Representation in latent space → Decoding → Output image
For a text-to-image generation using diffusion models, the model first generates random noise and continuously predicts how this noise representation should evolve in order to match the prompt. For many models, this happens in a latent space that compresses all the information about the image. Finally, the decoder transforms the last representation into an output image.
As you see, the description above sounds a bit complex, but its concept is very simple indeed:
The model has learned visual patterns through training, and applies this knowledge for generating an image based on a noisy or encoded representation.
What is AI image generation?
AI image generation is the process of creating or modifying visual data using machine learning algorithms based on instructions such as text prompts or other conditions.
You can ask for things like:
“A cinematographic picture of a rainy street of Mumbai during sunset time, wet streets, warm light coming from shops, realistic photography style.”
This is not just searching through the Internet for a similar image. Instead, your prompt becomes data used by the image generation algorithm to decide what kind of visual result should be produced.
There are various ways of doing that and Diffusion model is one of the popular techniques, however, there are also other ones like transformers and others. The specifics depend on the particular model you work with.
AI image generation has two different stages
One of the simplest misconceptions regarding image generation can be to confuse training and generation.
These are two different processes.
Stage 1: Training
During training, the model is presented with an enormous amount of visual data and understands the statistical relationships between the visual patterns and the corresponding information about them, such as text.
These relationships can include:
- objects
- shapes
- colours
- lighting
- textures
- composition
- styles
- spatial relationships
- visual concepts
- language associated with those concepts
Studies like CLIP showed that there is a way to connect images with language with the help of many image-text pairs. CLIP was trained on 400 million image-text pairs.
The neural network is thus not creating a simple dictionary like:
“cat” = this exact picture.
It is learning much richer statistical relationships.
Stage 2: Generation
Generation occurs once the model is trained.
You give the prompt.
The system understands the prompt, sets the parameters for the generation process, constructs or adjusts the internal representation, and generates the image.
With the diffusion-based pipeline approach, this typically includes iterative denoising.
This is important because the training process is not repeated with each Generate button press.
Step 1: Your prompt is converted into machine-readable information
However, the model cannot understand the above sentence:
“A futuristic Indian city during Diwali.”
the same way a human does.
Firstly, the text needs to be converted to numerical form. This is done by a text encoder in most image generation algorithms. The encoder transforms the prompt into embeddings: numerical form that contains all information required by the model.
Most systems use CLIP-like text encoders. Other systems utilize different language or multimodal encoders. Modern diffusion tools allow us to use models with different text – encoding arrangements, so there is no single universal encoder architecture.
Why does the text encoder matter?
Since the image requires more than just words.
Think about:
“A red umbrella next to a blue bicycle.”
Useful information would include:
- umbrella
- bicycle
- red
- blue
- beside
- relationships between those concepts
Improved conditioning will aid the generator in maintaining such associations more consistently.
This is a possible explanation for why various AI image generators have produced drastically different images from the same prompt.
Step 2: The prompt conditions the generation
The text encoding is used for guiding the creation of the image. When working within a diffusion process, the text information can affect the denoising process on several occasions.
Classifier-free guidance is one of the known methods where both conditional and unconditional outputs are utilized for guiding the generation towards the required condition.
We can look at the prompt as something that provides a direction but not actual instructions for drawing.
For instance, when the prompt is the following: “A red sports car on a mountain road at sunrise”
It is not a checklist like:
- Draw a rectangle.
- Add four wheels.
- Colour it red.
- Add mountains.
- Add sunrise.
Instead, the prompt influences the probability of different visual structures throughout the generation process.
Step 3: The model starts from noise
It is this aspect that gives the model its unique charm.
Rather than starting with a finished image, which can be edited one element at a time, the text-to-image model based on the diffusion approach can start with nothing but some random noise.
Imagine TV snow. At first, there is no coherent picture whatsoever. Gradually, the model transforms the random noise into something meaningful. And the key point is that the model has been trained to do just that.
During diffusion training, the image gets corrupted by more and more noise. The model learns to predict the process that undoes the corruption.Then, during generation, it acts in the opposite way.
Step 4: The model repeatedly refines the image
This is at the core of the diffusion generation process.
During each generation step, the model considers the current representation and determines how to modify it.
Theoretically:
Noise → slightly structured noise → composition → recognizable objects → details → final image
The model performs this operation a certain number of times through inference steps.
The specific algorithm will be dependent on the particular model and the scheduler used.
For instance, Hugging Face’s diffusion pipeline offers options like num_inference_steps, but with the caveat of potentially increasing computational cost in the process.
The key point is not the precise number of steps, but rather the iterative improvement process.
Step 5: Much of the work happens in latent space
Processing every pixel is costly. That is when latent diffusion comes into play.
Rather than repeatedly processing the full high-resolution image pixel by pixel, the process can instead represent the image in a compressed numerical form known as latent space. Latent space is the compact representation of the image. It is not just a compressed JPEG. Latent space is a learned representation that holds information needed to recreate visual structures.
Latent-diffusion work demonstrated that diffusing in the latent representation of a pretrained autoencoder could significantly cut down computational needs while preserving image generation quality. Thus, a simplified workflow looks as follows:
Image representation → compact latent → generation takes place here → compact latent→decoded image
One of the ways in which modern image generation systems can handle generation without manipulating each and every pixel at each step is due to latent diffusion.
Step 6: A neural network performs the generation work
In the process of iterative generation, the model itself can sometimes be a U-Net but increasingly is becoming a Diffusion Transformer (DiT) or other type of architecture.
It is another instance where older descriptions may have gone out of date.
There is no one-size-fits-all “architecture for an AI image generator” in the world.
For instance, the latest documentation by Hugging Face Diffusers mentions the use of either a U-Net or a diffusion transformer as the primary denoising component in a diffusion pipeline.
The task is still fundamentally the same:
Current representation + conditioning + generation timestep → prediction of movement towards the desired result.
The architecture for achieving this task is variable.
Step 7: The final representation is decoded into pixels
Once the generation step comes to the end of the process, it’s necessary to translate that representation into an ordinary image.
For the latent diffusion models, there is a decoder mechanism that will be able to decode the final latent representation into pixel space like variational autoencoder or VAE.
And that’s the reduced process pipeline:
Prompt → Text representation → Conditioning → Initial noise / generation step → Generation step → Clean latent representation → Decoder → Image
This is what you need to remember about.
The complete AI image-generation pipeline
Here is the process in one view:
| Stage | What happens |
| Prompt | You describe the desired image |
| Encoding | The prompt becomes numerical information |
| Conditioning | That information guides generation |
| Initialization | A diffusion system can begin from random noise |
| Generation | The model repeatedly predicts how the representation should change |
| Latent processing | Many systems perform this work in compressed latent space |
| Decoding | The final internal representation is converted into pixels |
| Output | You receive the generated image |
The exact implementation changes between models, but this is a useful mental model for understanding modern text-to-image systems.
Why does the same prompt produce different images?
This is another important factor. The starting noise used in diffusion pipelines is controllable through the use of a random seed. This is exemplified by Hugging Face’s Stable Diffusion documentation, which provides access to a generator to control the starting random latents. Change the starting point, and the process takes a new course.
Thus:
Same prompt + different starting conditions = potentially different image
This is useful because it lets you explore multiple interpretations of the same idea.
For example:
“A traditional Indian courtyard at sunrise”
could produce different:
- camera angles
- building layouts
- lighting
- colours
- architectural details
- compositions
while still staying within the same general prompt.
Why does AI sometimes get hands, text or object counts wrong?
And this is because image synthesis is different from human reasoning. The model is producing output based on patterns that it has learned from the conditioning signals. It is not necessarily going through a checklist like this one:
“There must be five apples in total, and the third apple must be behind the bowl.”
The above mentioned difference is why AI image models fail to do the following:
- exact object counts
- unusual spatial relationships
- complex interactions between objects
- small text
- logos
- precise geometry
- unusual anatomy
- culturally specific visual details
- consistency across multiple images
This failure rate is very much dependent on the model and tasks, hence, these should be seen as limitations of the model rather than an absolute truth about AI image generation.
CLIP itself, which is one of the fundamental vision-language models, exhibited limitations on systematic tasks like counting and detailed visual discrimination.
Why AI image generators can make mistakes even when the prompt is clear
A well-formulated prompt does not assure a deterministic output. Consider the following prompt:
“Three women from India standing next to a red car, with one woman carrying a blue umbrella.”
The model needs to account for multiple relations at once:
- three people
- Indian visual context
- a car
- red colour
- an umbrella
- blue colour
- who is holding the umbrella
- relative positions
- composition
- lighting
- style
The greater the number of relationships that a generation needs, the greater the chance that the generated output will be different from the precise instruction. This is because prompting is not merely a process of adding adjectives.
The relevant question is: What kind of information should the model know to differentiate the desired image from others?
Does AI image generation copy existing images?
This question requires a response which goes beyond both “yes” or “no.” A generative model usually doesn’t function like a search engine that fetches a similar training image and pastes it in your output. This generation process works with learned parameters of the model to generate new outputs.
But this does not mean that memorisation cannot happen at all. It has been found through research and behaviour of models that memorisation can occur in some cases. There is another question related to legality and ethics of how certain models have been trained with their data.
So here are three different questions:
- Does the generation process simply search a database of photographs?
No. - Can models memorise or reproduce specific training material in some circumstances?
Yes, this can occur. - Does the technical mechanism settle copyright or licensing questions?
No. Technical behaviour and legal rights are separate issues.
That distinction is much more useful than saying AI “copies everything” or “never copies anything.”
What is the difference between AI image generation and image editing?
Text-to-image generation refers to a technique where an image is generated from a prompt and the model’s representations learned. On the other hand, image-to-image generation involves taking an image and using that as an extra condition.
The following is a general process in image-to-image generation through diffusion:
- The input image is encoded.
- Noise is introduced into its latent representation.
- The prompt acts as an additional conditioning.
- The model then removes the noise.
- The decoder generates the output image.
Hugging Face’s image-to-image documentation describes this general process directly.
This makes image-to-image useful for tasks such as:
- altering visual style
- composition alteration
- reworking a scene
- generating variations
- converting a photograph
- maintaining certain elements while changing others
What about inpainting and outpainting?
Modern image-generation workflows can go beyond creating an entire image from scratch.
Inpainting
Inpainting modifies the selected part of the image.
For instance:
Change the background around the product to a contemporary office.
The model produces the selected part of the image based on the context from the whole image.
Outpainting
Outpainting is painting beyond the original extent of the image.
For instance:
Portrait photographs can be transformed into larger scenes.
This is basically the same idea as conditioning a model to generate something, except now the original image and the new section being created add to the inputs.
Diffusion is important, but it is not the only architecture
This is one of the most important updates to older explanations of AI image generation.
Diffusion models
Diffusion models learn how to create images via successive refinement from their initial noisy states.
Diffusion models continue to be a dominant class of image generation models and underlie many popular open-source diffusion frameworks.
Diffusion Transformers
Other recent models utilize a transformer model as the backbone of the denoising or generating module.
The mental model has an iterative nature, although the model architecture may be different.
Autoregressive image models
Another method involves representing an image using a series of tokens and predicting the tokens in succession, which is analogous to how language models predict text tokens.
The initial version of DALL·E by OpenAI, for instance, was claimed to be a transformer model capable of producing images using textual descriptions.
Other approaches
The field also includes:
- GANs
- VAEs
- flow-based approaches
- flow matching
- hybrid architectures
- specialised image-editing models
And what the practical takeaway should be is:
Do not assume that all the AI image generators out there work the same way as a Stable Diffusion model.
What does AI image generation mean for someone in India?
The technology used is globally available; however, the prompt and situation may be very local indeed.
Thus, for instance, a creator from India may find the need to apply an image generator to produce ideas for:
- Diwali Campaigns
- Indian Festivals
- restaurant marketing
- eCommerce products
- education
- social media content
- travel ideas
- architecture
- packaging concepts
- presentation slides
Instead of writing:
“Traditional festival scene.”
A better prompt could include information about the context:
“Editorial style photo of Diwali festival in an urban Indian house, warm lights, family scene, realistic evening lighting, natural skin tones, documentary photography.” This additional information does not automatically result in increased accuracy. The model has more information to consider.
For culturally specific images, there is still a need for human review. The model can create something that looks realistic but has inaccurate clothing, architecture, symbols or context.
How to write better AI image prompts
With knowledge of how generation occurs, prompt writing becomes easier. You don’t require some “magic words” that are not known to anyone else. Rather, write about what visual information really counts.
One such approach can be:
Subject + Environment + Composition + Lighting + Style + Important constraints
For example:
- Theme: Street food seller in India
- Setting: crowded evening market in Delhi
- Framing: mid-documentary style frame
- Lighting: warm lighting from market lamps above
- Style: realistic editorial photography
- Constraints: natural expressions, realistic proportions, showing food stall
Combined:
“Editorial photograph of an Indian street-food vendor on a busy evening market scene in Delhi, compositional medium shot, overhead market lights, natural expressions, realistic proportions, food stall details.”
It’s better than putting in all those generic quality adjectives in the prompt.
What happens when you change one word?
A change in the prompt may affect the conditioning information that is provided to the AI.
For instance:
“A small café in Mumbai at sunrise” vs. “A luxury café in Mumbai at sunrise”
The latter prompt affects the type of imagery that the model has to generate.
Replace: “photorealistic” with: “watercolor illustration”
and you are generating a completely different distribution of visual information. That is how the process of prompt iteration works. You are not asking the model to draw an exact CAD drawing. You are manipulating the conditions of the process of probabilistic generation.
Traditional image creation vs AI image generation
| Traditional workflow | AI image-generation workflow |
| Human creates or captures the image | Model generates an output from learned representations |
| Camera, drawing or 3D software may create the base | Prompt, image or other conditions initiate generation |
| Human directly controls many visual decisions | Human specifies conditions and evaluates outputs |
| Revisions can require significant manual work | Multiple variations can be generated quickly |
| Skills depend on the medium | Skills increasingly include prompting, selection and editing |
| Final quality depends heavily on human execution | Final quality depends on model capability plus human direction and review |
AI does not eliminate visual decision-making. It changes where some of that decision-making happens.
The simplest way to remember how AI image generation works
And if you are to remember one diagram at all, make sure to remember this one:
- You describe an image
- The system transforms the description into numerical representations
- These representations influence the generator
- A generation process starts from noise, tokens or other initial representation
- The process gradually creates the resulting image
- An output or decoder stage transforms the representation into an image
- You inspect, tweak, and re-generate
Diffusion-based systems are characterized by one key concept – that of iterative transformation of noise into a conditioned image. Latent diffusion makes this process computationally feasible due to operating in a compressed representation space.
Frequently asked questions
Q1. How does AI image generation work in simple words?
Ans. An AI image generator utilizes an already-trained model in converting user instructions, such as text and reference images, into an image. Diffusion AI image generators begin with noise and refine it iteratively using the instructions provided.
Q2. Does AI draw the image pixel by pixel?
Ans. Necessity is not implied. Many of today’s systems operate on the generation process through a compressed latent representation which is decoded into pixels. Other models use various methods of representing and generating data.
Q3. What is a diffusion model?
Ans. The diffusion model is a generative model trained on reversing the process of adding noise. In generating a sample, it could begin with random noise and evolve it to generate an output.
Q4. What is latent space in AI image generation?
Ans. Latent space is one such compressed numerical representation in most generative systems. Rather than carrying out the whole process of generating the image in full resolution, the process is carried out in the latent space and decoded later to create the image.
Q5. Why does AI make mistakes in images?
Ans. In the above model, there is an output of a visually plausible but not perfectly symbolically defined image. Complex interactions, accurate numbers, small text, abnormal anatomy, and precise instructions on placement may prove difficult for certain models.
Q6. Why does the same prompt generate different images?
Ans. The generation may rely upon the initial random state or seed. Even when the prompt does not change, altering the initial random state can cause a different outcome.
Q7. Can AI generate images from existing photos?
Ans. Yes. Image-to-image models can take an image already existing and then alter it based on a prompt.
Q8. Is AI image generation the same as image search?
Ans. Image retrieval searches for already present images from the index database. Generative image generation uses a trained model to generate or transform images.
Q9. Does every AI image generator use diffusion?
Ans. No. There is diffusion, which is one of the leading techniques; however, image generation models can also employ autoregressive, flow-based, transformer-based, and even hybrid solutions.
Final takeaway
Image generation with AI seems like child’s play on the surface:
Type a prompt → get an image.
However, below the hood, an AI model does a lot more exciting things than that. It transforms your prompt into numerical form, conditions a generation algorithm with the help of numerical form, builds the visual structure step by step, and finally turns its internal representation into the image you see.
For diffusion models, the way to conceptualize the process is:
Prompt → Conditioning → Noise → Iteration → Latent space → Decoding → Image
The technical details vary from model to model, but knowing this pipeline will allow you to understand most of the phenomena experienced by users: the importance of prompts, the influence of seeds on the result, the possibility of image manipulation, the complexity of certain instructions, and the peculiarities of new models despite similar interfaces. After comprehending all of that, AI image generation becomes comprehensible no longer.


