

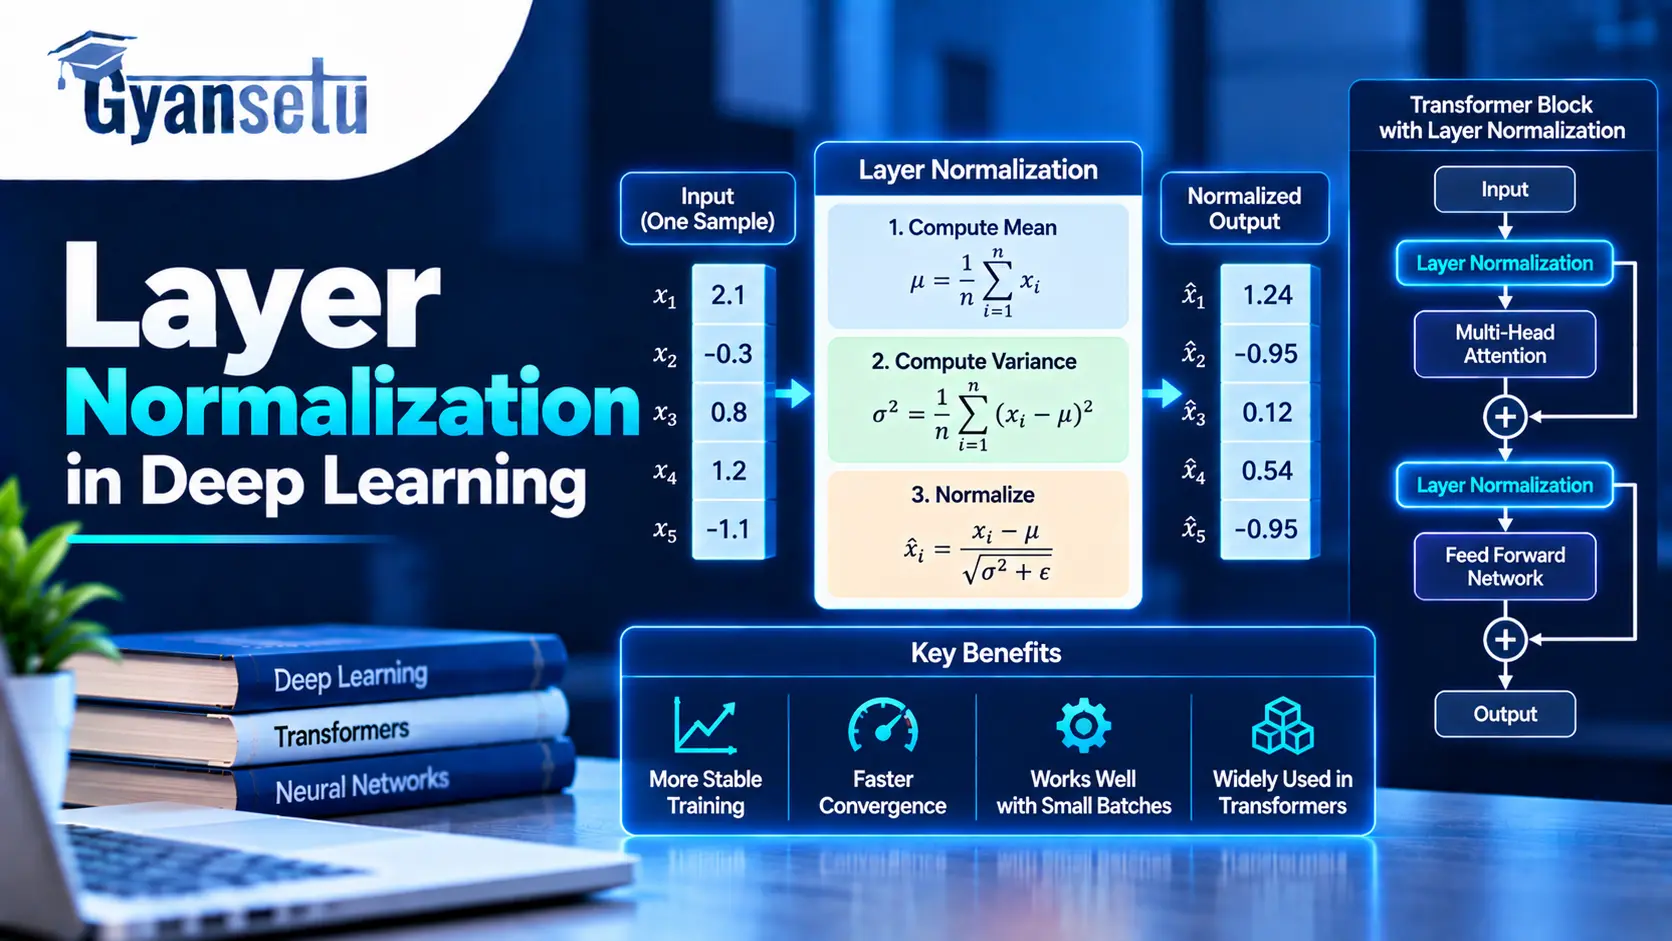
Layer normalization is an approach that normalizes the input to a neural network layer by calculating the mean and the variance over the feature dimension of each training example and not over the batch. This method was proposed by Ba, Kiros, and Hinton in 2016 at the University of Toronto for stabilizing training in recurrent neural networks.
The other type of normalization, known as batch normalization, was proposed one year earlier by Ioffe and Szegedy, and the only difference between the two approaches is the dimension in which the statistics are calculated.
What Will I Learn?
What Is Layer Normalization?
The Layer Normalization algorithm involves calculating the mean and variance of all features in a particular training example, after which it normalizes them to have zero mean and unity variance. This is done for each individual example in the batch separately.
This approach addresses an issue that arises in deep neural nets known as internal covariate shift, where the distribution of the inputs to the layers change, making it difficult to train and sometimes leading to exploding/vanishing gradients.
Three properties define the technique:
- It is normalized along the feature dimension rather than the batch axis.
- It requires no running statistics while testing, unlike Batch Normalization.
- There are two learnable parameters applied after the normalization process: scale and shift.
Agentic AI Course
Average time:6 month(s) + Lifetime Access
Skills you’ll build: Autonomous Decision-Making, Reinforcement Learning, Multi-Agent System Design, Natural Language Understanding & Generation, API Integration & Autonomous Execution, Goal-Oriented Planning & Problem Solving
The Math Behind Layer Normalization
Layer Normalization applies three sequential operations to the output of a layer: compute statistics, normalize, then scale and shift. The following example uses a hidden layer with four features, H = 4.
Step 1 — Compute the mean and variance per example
A layer produces the output vector z = [2.0, 6.0, 4.0, 12.0] for one training example. The mean and variance are calculated across these four values only.
| Quantity | Formula | Result |
| Mean (μ) | (1/H) × Σ zᵢ | (2.0 + 6.0 + 4.0 + 12.0) / 4 = 6.0 |
| Variance (σ²) | (1/H) × Σ (zᵢ − μ)² | (16 + 0 + 4 + 36) / 4 = 14.0 |
Step 2 — Normalize each feature
Each value subtracts the mean and divides by the standard deviation. A small constant, epsilon (ε), prevents division by zero when variance is near zero. A common value is ε = 1e-5.
zi=zi-2+
| Original value | Normalized value |
| 2.0 | −1.0690 |
| 6.0 | 0.0000 |
| 4.0 | −0.5345 |
| 12.0 | 1.6036 |
Step 3 — Scale and shift the normalized values
Two learnable parameters, gamma (γ) for scale and beta (β) for shift, are applied per feature so the layer can restore any distribution the network needs.
With γ = 2.0 and β = 1.0, the final output becomes [−1.1380, 1.0000, −0.0690, 4.2072]. Gamma and beta start at 1 and 0 respectively and update during backpropagation like any other network weight.
Where Layer Normalization Sits Inside a Transformer
The original 2017 Transformer model has Layer Normalization applied after the residual connection of the sublayers – an approach that has been termed “Post-LN.” In this case, the output of the sublayer is added to its input and then normalized.
On the other hand, GPT-2 and newer models have Layer Normalization applied before the sublayers – an approach termed “Pre-LN.” In 2020, Xiong et al. observed that the gradients from Pre-LN models exhibit better behavior at the beginning of training, making the warm-up phase unnecessary for these models.
This means that Pre-LN models are easier to train than Post-LN models in deep networks because of the absence of a learning rate warm-up phase. That is why most modern language models since 2019 have adopted the Pre-LN approach.
Implementing Layer Normalization in PyTorch
The torch.nn.LayerNorm module implements the three steps above in one call.
import torch

import torch.nn as nn

layer_norm = nn.LayerNorm(normalized_shape=512)

hidden_states = torch.randn(8, 20, 512)  # (batch, sequence, features)

output = layer_norm(hidden_states)
The normalized_shape argument must match the size of the last dimension of the input tensor. Passing a mismatched value produces a runtime error stating the expected and actual tensor shapes. Two default parameters control behavior:
- eps (default 1e-5) — the epsilon constant from Step 2.
- elementwise_affine (default True) — enables the learnable gamma and beta parameters from Step 3. Setting this to False normalizes the input without rescaling it.
Layer Normalization vs. Batch Normalization vs. RMSNorm vs. Group Normalization
Four normalization methods are used across current neural network architectures. Each computes its statistics over a different set of values.
| Method | Statistics computed over | Depends on batch size | Learnable parameters | Typical use case |
| Layer Normalization | All features of one example | No | Scale (γ) and shift (β) | Transformers, RNNs |
| Batch Normalization | One feature across the batch | Yes | Scale (γ) and shift (β) | Convolutional networks |
| RMSNorm | Root mean square of features, no mean subtraction | No | Scale (γ) only | Large-scale language models |
| Group Normalization | Features within a channel group | No | Scale (γ) and shift (β) | Vision models with small batches |
RMSNorm, proposed by Zhang and Sennrich in 2019, is an approach that eliminates the mean centering operation performed in the Layer Normalization technique and only uses the root mean square normalization on the input data.
Why Modern Language Models Use RMSNorm — and When Layer Normalization Performs Better
RMSNorm is more efficient computationally since it does not involve mean subtraction, which according to the RMSNorm research paper results in a 7% to 64% saving in training/run time, with 64% being an upper limit, not average for particular network architectures tested at the time of writing the paper.
In 2019, the T5 model introduced by Google used RMSNorm. RMSNorm was also utilized by PaLM, LLaMA, and Gemma models; however, they did not inherit RMSNorm from the T5 architecture. GPT-2 and GPT-3 make use of regular Layer Normalization.
Layer Normalization keeps one practical benefit that is not replicated by RMSNorm: its output activations center around zero. This aspect is important for quantization, which means the transformation of model weights into low-precision number formats, such as fp8, to save memory and speed up inference. The FP8 format is the most precise at zero; hence, centering activations at zero loses less information during quantization. It is only a reasonable hypothesis, not proven by any benchmarks yet, that the activations that are not centered may drift from zero in deeper layers.
The difference in performance becomes less prominent on modern devices. When both normalizations are implemented in a GPU kernel format such as Triton, benchmark tests report almost identical execution speed. The initial performance boost provided by RMSNorm only works for unoptimized implementations.
How to Choose the Right Normalization Method

The choice depends on three factors: batch size stability, hardware target, and quantization requirements.
- If the batch size changes during training and inference or is equal to one, apply either Layer Normalization or RMSNorm. Batch Normalization works efficiently only with a sufficiently big and stable batch size.
- In case the network is a convolutional network, and the batch size is big enough and is fixed, use Batch Normalization. It is still the default option for such architectures.
- In case the quantization is applied to the target deployment platform (fp8 or bf16), use Layer Normalization. It produces zero-centered activation functions, which helps to decrease the quantization error.
- If training speed is the key requirement of GPU hardware, and quantization is not an issue, use RMSNorm with efficient implementation via a kernel function.
- If the network works with small fixed-size batches of images, use Group Normalization instead of Batch Normalization.
Agentic AI Course
Average time:6 month(s) + Lifetime Access
Skills you’ll build: Autonomous Decision-Making, Reinforcement Learning, Multi-Agent System Design, Natural Language Understanding & Generation, API Integration & Autonomous Execution, Goal-Oriented Planning & Problem Solving
Advantages and Limitations of Layer Normalization
Advantages:
- Independently of batch size. The statistics are computed for each example, therefore it works with a batch size of just one.
- No inference-time statistics. In contrast to Batch Normalization, there is no need for maintaining running statistics from training to inference time.
- Stable with respect to sequence length. Some architectures that process sequences utilize this feature, among which recurrent networks, Transformers, and speech recognition systems.
- Zero mean outputs. This feature decreases precision losses when converting to low-bit representation.
Limitations:
- Effectiveness dependent on architecture. Batch Normalized ConvNets usually have better performance with larger batch sizes.
- Additional computations per layer. Every normalizing operation adds two more computations (calculation of mean and variance) to the computation in the layer itself.
- Loss of activation magnitudes. The normalization procedure loses information regarding the magnitudes of the activations, which may have to be learned by the parameters again.
Frequently Asked Questions
Q1. Is Layer Normalization the same as Batch Normalization?
Ans. Layer Normalization computes statistics over features of one training example, while Batch Normalization computes statistics over the batch dimension of one feature.
Q2. Do current large language models use Layer Normalization or RMSNorm?
Ans. Model families are different: GPT-2 and GPT-3 utilize Layer Normalization, while T5, LLaMA, and Gemma use RMSNorm.
Q3. Is RMSNorm faster than Layer Normalization?
Ans. RMSNorm is faster than Layer Normalization in case of unoptimized implementation, as it doesn’t require mean subtraction. However, when using an optimized GPU kernel (like the kernel implemented in Triton), the benchmarks show that the performance gap is minimal.
Q4. Does Layer Normalization work with a batch size of one?
Ans. Yes, it calculates statistics per-example, thus the batch size does not affect its calculation.
Q5. What is the purpose of epsilon in the Layer Normalization formula?
Ans. Epsilon is a small constant (usually 1e-5) which is added to the variance before applying square root.
Q6. Does Layer Normalization improve or hurt quantization?
Ans. It helps with better results in quantization. Its output activations are close to zero, which corresponds to the most precise range of low-bit formats like fp8.
Key Takeaway
Layer normalization performs per example statistics to ensure that the layer inputs remain constant irrespective of the size of the batch. There is also the RMSNorm that serves as a faster and simplified version of the Layer Normalization technique that is used in most existing large language models.


