

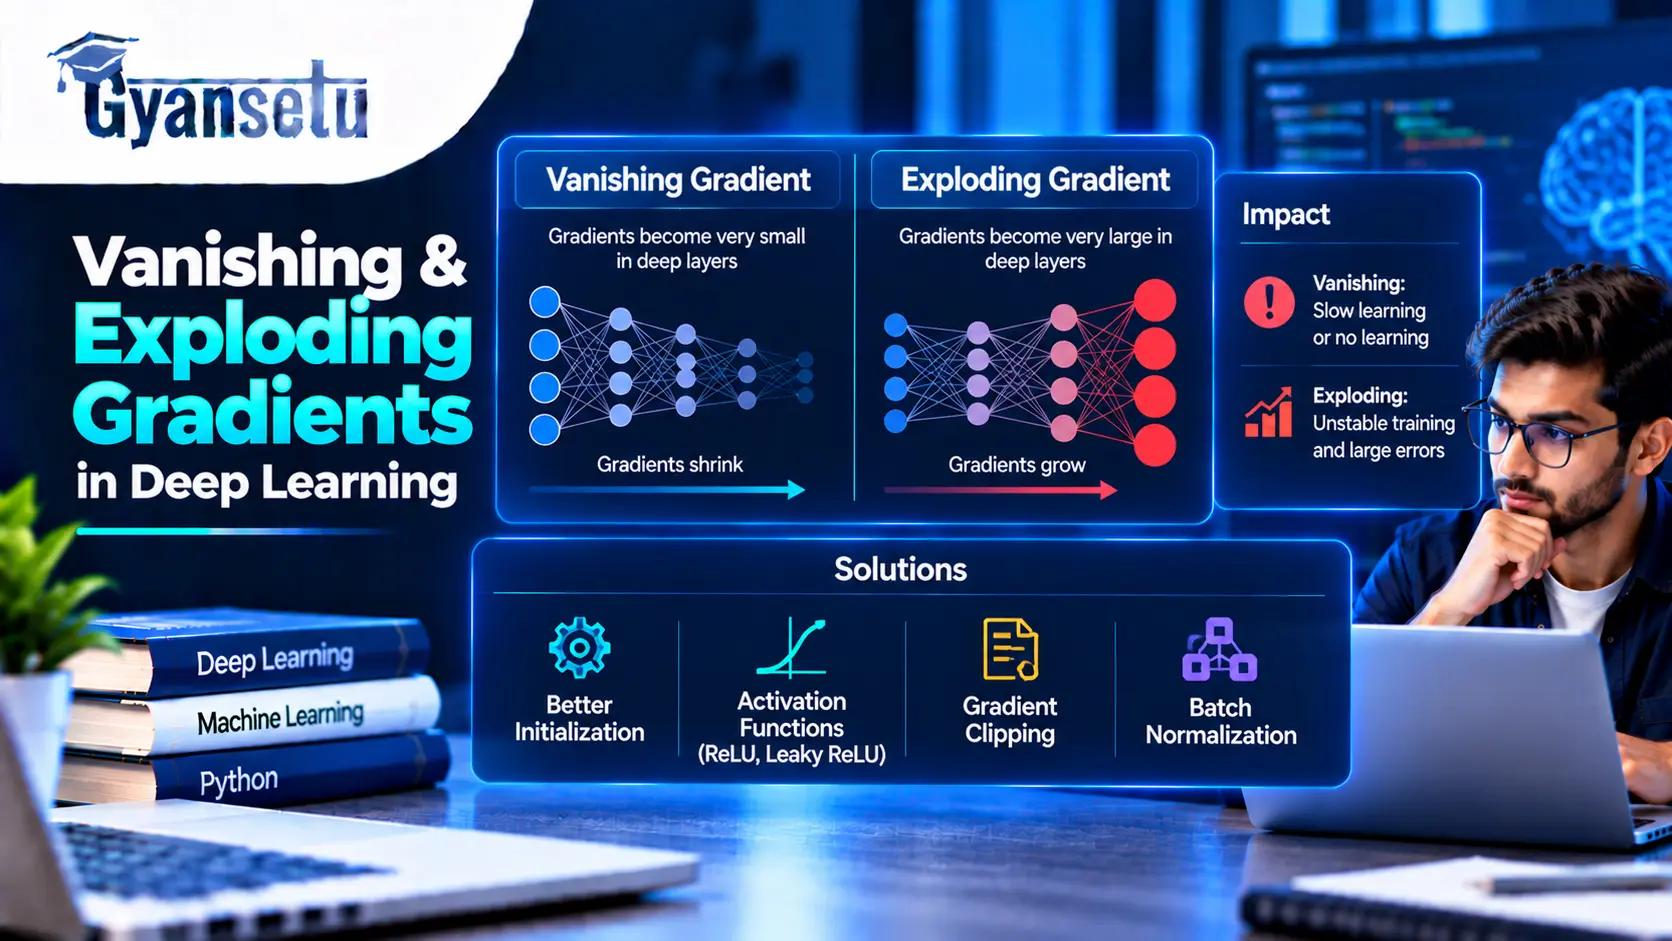
The 20-layer sigmoid network feeds a gradient that is 450 trillion times weaker than the last layer receives to the first layer. The network fails to learn. Vanishing and exploding gradients are failures in the training process of deep learning in which the gradients propagated backward become infinitesimally small or infinite as one proceeds from one layer to another, thus preventing learning in the early layers or leading the loss function to infinity. This article explains how to determine the failure a network experiences before implementing the appropriate remedy.

Vanishing and exploding gradients issue has been studied for the first time by Sepp Hochreiter in his diploma thesis of 1991 from Technical University of Munich. Later in 1994, Yoshua Bengio, Patrice Simard, and Paolo Frasconi described it in the case of recurrent networks. Among current solutions, ReLu activations, Xavier & He initialization, residual blocks, normalization layers, and LSTM are to be mentioned.
What Will I Learn?
What Are Vanishing and Exploding Gradients?
Vanishing gradients occur where the gradients approach zero during backpropagation, whereas exploding gradients occur where the gradients increase exponentially to generate large weight updates. Both vanishing and exploding gradients arise due to the same phenomenon of repeated multiplication during backpropagation.
| Attribute | Vanishing gradients | Exploding gradients |
| Gradient behavior | Shrinks toward 0 | Grows toward infinity |
| Main cause | Per-layer factors below 1 | Per-layer factors above 1 |
| Typical trigger | Sigmoid or tanh saturation, small weights | Large weights, high learning rate |
| Loss symptom | Flat plateau early in training | Spikes, oscillation, NaN |
| Layers hit first | Early layers near the input | All layers, often suddenly |
| Common in | Deep MLPs, vanilla RNNs | RNNs, unnormalized deep nets |
| First fix to try | ReLU + He init, residual connections | Gradient clipping, lower learning rate |
The Vanishing Gradient Problem
Vanishing gradients refer to the failure to transfer the signal back through the layers and thus failing to adjust the weights of the earlier layers, while the remaining layers continue to learn. Early layers that identify primitive features such as edges of an image or word pattern from text will remain unchanged from their initialization values.
The Exploding Gradient Problem
Exponential growth in the gradient values obtained during backpropagation leads to exploding gradients where the gradients grow at an exponential rate. As a result, the loss fluctuates, the weights overflow, and the training becomes NaN. In fp16 floating point precision, any value above 65,504 overflows into infinity.
Agentic AI Course
Average time:6 month(s) + Lifetime Access
Skills you’ll build: Autonomous Decision-Making, Reinforcement Learning, Multi-Agent System Design, Natural Language Understanding & Generation, API Integration & Autonomous Execution, Goal-Oriented Planning & Problem Solving
Why Gradients Vanish or Explode
Gradient vanishing/exploding occurs due to multiplication of backpropagation by one factor per layer, and when many factors are multiplied that are less than 1 then their exponential shrinkage occurs, and for factors greater than 1 their exponential growth occurs.
Backpropagation Multiplies One Factor Per Layer
This results in the fact that the gradient with regard to layer 1 becomes the multiplication of the derivative of each layer after layer 1. This is expressed as follows, when there are n layers:
Each term ∂aₖ/∂aₖ₋₁ is a Jacobian matrix. It contains the layer’s weights multiplied by the activation function’s derivative. The size of that Jacobian decides whether the signal shrinks or grows at that layer.

What 20 Layers Do to a Gradient
With a per-layer factor of 0.25, a gradient gets reduced to 9.1 x 10⁻¹³ with 20 layers, whereas a factor of 1.5 increases it by 3,325. The table that follows makes use of 0.25 since it represents the largest derivative of the sigmoid.
| Layers | 0.25ⁿ (sigmoid ceiling) | 1.5ⁿ (factor above 1) |
| 5 | 9.8 × 10⁻⁴ | 7.6 |
| 10 | 9.5 × 10⁻⁷ | 57.7 |
| 20 | 9.1 × 10⁻¹³ | 3,325 |
| 50 | 7.9 × 10⁻³¹ | 6.4 × 10⁸ |
A 50-layer sigmoid network loses 30 orders of magnitude of gradient signal, even under the best case where every unit sits at its steepest point.
Saturating Activations: Sigmoid and Tanh
Sigmoid and Tanh functions produce vanishing gradients due to their maximum derivatives of 0.25 and 1 respectively, with their values approaching zero for larger inputs. For sigmoid, σ'(z) = σ(z)·(1−σ(z)), the derivative is maximal, being equal to 0.25 when z = 0. For z = 5, the derivative is 0.0066. The derivative of tanh can be maximal, i.e. equal to 1 only at z = 0 and falls below 0.02 at z = 3.

Glorot and Bengio showed in their 2010 AISTATS paper that sigmoid networks with standard random initialization push top hidden layers into saturation early in training.
Weight Scale and Poor Initialization
Gradient control with weight scale prevents exploding gradients – when the weight scale is too high, each layer will multiply the gradient by some number greater than one, and the result will be an exponential function of the layer depth. The weights sampled from N(0, 1) in the 64-neuron layer will have each Jacobian’s spectral scale equal to about 8.
The symmetry issue is another issue resulting from zero initialization. The gradient received by each unit within a layer is identical, hence the units remain similar. Random numbers disrupt the symmetry, although a variance equivalent to the width of the layer must be used.
Why RNNs Suffer Most
RNNs are particularly affected due to the effect of backpropagation through time, which multiplies the same weight matrix of the recurrence at each time step, meaning that a 100 time step sequence is equivalent to a 100 layer net having shared weights. According to Bengio et al., in 1994, such multiplication makes it difficult to capture long-term dependency in the sequence using gradient descent. According to Razvan Pascanu et al., in 2013 at ICML conference, the eigenvalue of the matrix determines the fate.
How to Detect Vanishing and Exploding Gradients
Identify gradient issues by monitoring the norm of the gradient of each layer throughout the training process; low values of the norms of the early layers suggest vanishing gradients, whereas large values or infinity/NaN suggest exploding gradients. The loss plot does not distinguish between the two issues.
Symptoms in the Loss Curve and Weights
A flat loss curve from the first epochs points to vanishing gradients, while sudden loss spikes and NaN values point to exploding gradients.
| Signal | Vanishing | Exploding | Healthy |
| Loss curve | Flat plateau | Spikes, then NaN | Smooth decrease |
| Early-layer weights | Barely change | Change wildly | Change steadily |
| First/last grad-norm ratio | Below 10⁻⁴ | Near 1 but huge values | 0.1 to 10 |
| Total grad norm | Near 0 | Jumps 10× or more between steps | Stable band |
| Activations | Saturated at 0 or 1 | Overflow to inf | Mixed range |
The thresholds above are working heuristics from practice, not published standards.
Log Per-Layer Gradient Norms in PyTorch
Read each parameter’s .grad after loss.backward() and before optimizer.step(), then compare the first and last layer norms. The function below returns one L2 norm per weight tensor.
python
import torch

def layer_grad_norms(model):
    return {name: p.grad.norm(2).item()
            for name, p in model.named_parameters()
            if p.grad is not None and name.endswith("weight")}

loss.backward()
norms = layer_grad_norms(model)
values = list(norms.values())
print(f"first layer: {values[0]:.2e}  last layer: {values[-1]:.2e}")
print(f"first/last ratio: {values[0] / values[-1]:.2e}")
optimizer.step()
optimizer.zero_grad()
A first/last ratio below 10⁻⁴ indicates vanishing gradients. A NaN in any value indicates an overflow that must be traced to its first layer.
Read Gradient Histograms in TensorBoard or W&B
TensorBoard and Weights & Biases plot gradient histograms per layer over time, which shows whether distributions collapse toward zero or spread outward. In TensorBoard, call writer.add_histogram(name, p.grad, step) inside the training loop. In Weights & Biases, call wandb.watch(model, log=”gradients”, log_freq=100) once after building the model.
A vanishing layer shows a histogram that narrows into a spike at 0 over steps. An exploding layer shows tails that widen by orders of magnitude between logging points.

Test Results: One 20-Layer Network, Four Setups
In a controlled experiment, a 20-layer network trained using the sigmoid function provided a first layer with a gradient magnitude 4.5 × 10¹⁴ times less than the last layer, while ReLU using He initialization resulted in gradients differing in magnitude by no more than a factor of 1.3.
Test parameters: a 20-layer multilayer perceptron with 64 neurons in each layer, batch size 256, mean squared error loss, and seed 0, executed in NumPy. Numbers are layer-wise L2 norm of weight gradients after one backward pass at initialization.
| Setup | Layer 1 norm | Layer 10 norm | Layer 20 norm | Layer 1 ÷ Layer 20 | Result |
| Sigmoid + default uniform init | 5.8 × 10⁻¹⁸ | 1.2 × 10⁻¹¹ | 2.6 × 10⁻³ | 2.2 × 10⁻¹⁵ | Vanishing |
| Sigmoid + residual connections | 0.19 | 0.57 | 1.00 | 0.19 | Fixed |
| Tanh + Xavier init | 0.066 | 0.072 | 0.071 | 0.92 | Stable |
| ReLU + He init | 0.22 | 0.37 | 0.27 | 0.81 | Stable |
| ReLU + weights N(0, 1) | 5.5 × 10²⁷ | 2.2 × 10²⁸ | 6.4 × 10²⁸ | 0.087 | Exploding |
There are three observations. First, residual connections fixed the gradient problem in the sigmoid network with no change in activation function. Second, tanh and relu networks remained stable if the initialization was set appropriately relative to their activation functions. Third, the N(0, 1) network gave gradients of order 10²⁸ in each layer, which would cause an immediate overflow in fp16.
The scale used for the residual connection in this experiment was 1/√20. Using unscaled residual connections with He initialization leads to norms being magnified by about 10× between layer 1 and layer 20.
How to Fix Vanishing and Exploding Gradient Problems in Deep Learning
Solve the issue of vanishing and exploding gradients in deep learning through seven techniques: use of non-saturating activation functions, initialization, residual connections, normalization, gradient clipping, gated recurrent units, and learning rate warm-up. The detection process determines which technique to apply first.
1. Use Non-Saturating Activations (ReLU, Leaky ReLU, ELU, GELU)
Use ReLU or any of its variants instead of sigmoid and tanh in hidden layers because the derivative of ReLU is 1 when inputs are positive. There is only one drawback to ReLU: when inputs are always negative, the units become zero and cease to learn. This is referred to as dying ReLU.
| Activation | Derivative range | Saturates? | Dead units? | Typical use in 2026 |
| Sigmoid | 0 to 0.25 | Both sides | No | Output layer for binary tasks |
| Tanh | 0 to 1 | Both sides | No | LSTM and GRU gates |
| ReLU | 0 or 1 | No, for positive inputs | Yes | CNNs, MLPs |
| Leaky ReLU | α or 1, often α = 0.01 | No | No | GANs, deep CNNs |
| ELU | Above 0 to 1 | Negative side only | No | Deep MLPs |
| GELU | Smooth, about −0.17 to 1.13 | No | No | Transformers such as BERT and GPT-style models |
GELU was introduced by Dan Hendrycks and Kevin Gimpel in 2016.
2. Match Initialization to the Activation (Xavier, He, LeCun)
Assign weights according to their activation function, such that Xavier weights are used with tanh and sigmoid activations, while He weights are used for ReLU and similar types, and LeCun for SELU. This method ensures that the signal variance remains consistent between layers.
| Scheme | Weight variance | Pair with | Source | PyTorch call |
| Xavier / Glorot | 2 / (fan_in + fan_out) | Tanh, sigmoid | Glorot & Bengio, 2010 | nn.init.xavier_uniform_ |
| He / Kaiming | 2 / fan_in | ReLU, Leaky ReLU | He et al., 2015 | nn.init.kaiming_normal_ |
| LeCun | 1 / fan_in | SELU | LeCun et al., 1998 | nn.init.kaiming_normal_ with nonlinearity=”linear” |
The factor of 2 in He initialization compensates for ReLU setting half of its inputs to zero.
python
import torch.nn as nn

def init_weights(module):
    if isinstance(module, nn.Linear):
        nn.init.kaiming_normal_(module.weight, nonlinearity="relu")
        nn.init.zeros_(module.bias)

model.apply(init_weights)
3. Add Residual Connections
By providing an identity mapping, y = x + F(x), residual connections solve the problem of vanishing gradients where the local derivative is given as 1 + F′(x). The researchers at Microsoft developed the concept of residual networks in 2015, when their 152-layer deep ResNet was able to win the ILSVRC 2015 image classification task. In the experiment performed here, the introduction of residual paths helped to improve the gradient first/last ratio of a sigmoid network to 0.19.

4. Normalize Layers: BatchNorm, LayerNorm, RMSNorm
Normalization layers ensure that activations have zero mean and unit variance, preventing the input from entering saturated regions while keeping the gradient magnitude constant. There are three types of normalization layers that normalize on different axes.
- Batch Normalization normalizes each feature within the batch. Sergey Ioffe and Christian Szegedy proposed it at Google in 2015. It fails for batch size 1 to 4 as batch statistics become noisy.
- Layer Normalization normalizes across features for each sample separately. Jimmy Lei Ba, Jamie Ryan Kiros, and Geoffrey Hinton introduced it in 2016. It works for all batch sizes and is useful for RNNs and transformer layers.
- RMSNorm scales using root mean square normalization alone without centering. Biao Zhang and Rico Sennrich proposed it in 2019. It is widely used in large language models as an alternative to LayerNorm.

5. Clip Gradients by Norm
Norm-based gradient clipping scales the entire gradient vector if the L2 norm of the vector is greater than a certain threshold, limiting the magnitude of the vector but preserving its direction. This approach was suggested for RNNs by Pascanu, Mikolov, and Bengio in 2013. Threshold values of 1.0 are typical defaults in training of large language models.
Unlike norm-based gradient clipping, value-based clipping sets an upper bound on each component of the vector independently, for example, from −1 to 1. Thus, it alters the direction of the gradient vector.
python
loss.backward()
total_norm = torch.nn.utils.clip_grad_norm_(model.parameters(), max_norm=1.0)
if not torch.isfinite(total_norm):
    optimizer.zero_grad()   # skip this batch
else:
    optimizer.step()
optimizer.zero_grad()
clip_grad_norm_ returns the total norm measured before clipping. Log this value on every step; a rising trend warns of instability before the loss reaches NaN.
6. Use Gated Units: LSTM and GRU
In LSTM and GRUs, there is no problem of vanishing gradient due to the additive cell state update which transfers the information and hence the gradient scaling is controlled via forget gate instead of repeated multiplication of weight matrices. The LSTM was first proposed by Sepp Hochreiter and Jürgen Schmidhuber in 1997. The forget gate was later added by Felix Gers, Jürgen Schmidhuber and Fred Cummins in 2000.
The LSTM cell state update is cₜ = fₜ ⊙ cₜ₋₁ + iₜ ⊙ c̃ₜ. When the forget gate fₜ stays near 1, the gradient passes through many time steps with little decay. LSTMs still need gradient clipping, because the gates do not prevent exploding gradients.

7. Lower the Learning Rate and Add Warmup
Warm up of the learning rate helps prevent the phenomenon of exploding gradients in the initial training steps by gradually increasing the learning rate from a low value. Adaptive optimization algorithms like Adam approximate gradient variance based on very few examples during the early training steps, making the initial updates unstable. The Transformer paper by Vaswani et al., 2017, suggested using 4,000 warm-up steps. Facebook AI Research, Goyal et al., trained ResNet-50 with a batch size of 8,192 using 5-epoch warm-up, 2017.
Agentic AI Course
Average time:6 month(s) + Lifetime Access
Skills you’ll build: Autonomous Decision-Making, Reinforcement Learning, Multi-Agent System Design, Natural Language Understanding & Generation, API Integration & Autonomous Execution, Goal-Oriented Planning & Problem Solving
Which Fix to Use for MLPs, CNNs, RNNs, and Transformers
Firstly, it depends on the architecture: ReLU with He initialization for MLPs, residual connections with BatchNorm for CNNs, LSTM or GRU with clipping for RNNs, and Pre-LN with warmup and clipping for transformers.
| Architecture | Most likely problem | Fix first | Add next | Avoid |
| Deep MLP | Vanishing | ReLU + He init | BatchNorm or LayerNorm | Sigmoid in hidden layers |
| CNN | Vanishing past about 20 layers | Residual connections | BatchNorm | Xavier init with ReLU |
| RNN | Both | LSTM or GRU | Norm clipping at 1–5 | Long vanilla-RNN sequences |
| Transformer | Exploding, loss spikes | Pre-LN or RMSNorm | Warmup + clipping at 1.0 | Post-LN at large depth without warmup |
| Any, small batch | Unstable statistics | LayerNorm or GroupNorm | Gradient clipping | BatchNorm at batch size 1–4 |
Vanishing and Exploding Gradients in 2026 Model Training
In large model training by 2026, exploding gradients remain a problem in the form of loss spikes and numeric overflow, although residual streams and normalization have largely eliminated vanishing gradients in common network designs.
Pre-LN Transformers and the Residual Stream
In the Pre-LN transformer, layer normalization occurs prior to each attention and feed-forward module, allowing for a clean residual connection and stable training without the need for warmup. In their ICML 2020 paper, Ruibin Xiong et al. prove that the original Post-LN architecture generates massive gradients right near the output layer during initialization. The majority of LLMs released after 2020 adopt Pre-LN or Pre-RMSNorm.
Mixed Precision: bf16, fp16, and Loss Scaling
However, mixed precision training could give rise to a misconception of the vanishing or exploding gradient due to underflowing below 6 × 10⁻⁸ and overflowing above 65,504. In 2018, loss scaling was proposed by Paulius Micikevicius et al., researchers from NVIDIA and Baidu, which consists of multiplying the loss prior to backward pass to prevent the loss from being underrepresentable by FP16. With eight exponent bits, bfloat16 has the same range as fp32 and hence loss scaling is not required.
Loss Spikes in Large Model Training
Loss spiking is referred to as the unexpected increase in the loss value when running large-scale models, which can be controlled through the use of gradient clipping, low learning rate, and the start from a previously saved checkpoint. As indicated in the Google PaLM report of 2022, around 20 such cases of loss spiking have been encountered during training.
A Short History of the Gradient Problem
The issue of gradients was recognized back in 1991 and has been resolved step-by-step during three decades through gates, initializations, normalization, and residual connections.
- 1991: Sepp Hochreiter examines vanishing gradients in his diploma thesis.
- 1994: Bengio, Simard, and Frasconi demonstrate that long dependencies are difficult to learn using gradient descent.
- 1997: The LSTM was introduced by Hochreiter and Schmidhuber.
- 2010: Glorot and Bengio introduce Xavier initialization.
- 2013: Pascanu, Mikolov, and Bengio introduce gradient clipping.
- 2015: He initialization, ResNet, and Batch Normalization were introduced.
- 2016: Layer Normalization is introduced.
- 2020: Xiong et al. examine Pre-LN transformers.
Common Mistakes When Fixing Gradient Problems
Common mistakes include incorrect initialization, usage of BatchNorm for small batches, value clipping where it should have been norm clipping, and clipping that conceals a data problem. Here, each of these mistakes comes with a clear fix.
- Using Xavier Initialization with ReLU activation. Variance from Xavier is approximately half of that required by ReLU, resulting in diminishing signals when network depth increases. Use He Initialization.
- Using BatchNorm with batch size between 1 and 4. Batch statistics become noisy. Use LayerNorm or GroupNorm.
- Using value clipping for exploding gradients. It changes the gradient direction. Use clip_grad_norm_.
- Clipping without checking inputs. A NaN in the input data produces NaN gradients that clipping cannot fix. Run torch.isnan(batch).any() on suspect batches.
- Setting a high learning rate with ReLU. Large updates push units into permanently negative inputs, which kills them. Lower the rate or add warmup.
- Reading only the loss curve. A flat loss can come from a bad learning rate or wrong labels. Confirm with per-layer gradient norms.
- Log first and last layer gradient norms every 100 steps
- Log total gradient norm every step
- Confirm the initialization scheme matches the activation
- Use norm clipping for RNNs and transformers
- Use bf16 or loss scaling for mixed precision
- Check input batches for NaN when loss turns NaN
Frequently Asked Questions
Q1. What is the vanishing gradient problem in simple terms?
Ans. Vanishing gradients mean that during backpropagation, the earlier layers get such small gradients that the parameters do not change any further. Backpropagation is a product of a number of factors for each layer; thus, with most of the factors being less than 1, the whole product will tend to become very small.
Q2. What causes exploding gradients?
Ans. Exploding gradients result from multiplicative constants greater than 1 per layer, normally due to high variance of weights, a very high learning rate, or the biggest eigenvalue of the recurrent weight matrix being greater than 1. The gradient increases exponentially with the depth of the layers or the length of the sequence.
Q3. How do you know if gradients are vanishing or exploding?
Ans. Keep track of the L2 norm of the L2 gradient for each layer after loss.backward(). A first layer norm which is orders of magnitude smaller than the last layer norm is a sign of vanishing gradients. A total norm that increases by 10× or more between steps, or becomes infinite/NaN, is a sign of exploding gradients.
Q4. Does ReLU solve the vanishing gradient problem?
Ans. ReLU helps minimize the issue of vanishing gradients since the derivative of ReLU is always 1 for all positive values of x. Initialization of ReLU is required in order for the function to perform in deep neural networks. ReLU can cause dead neurons due to zero gradients, which do not occur in Leaky ReLU, ELU, and GELU.
Q5. Why are RNNs more prone to vanishing gradients?
Ans. Vanishing gradients are more common in RNNs due to backpropagation through time since this involves multiplying by the same matrix at each time step. Thus, a sequence of 100 time steps is equivalent to a 100-layer neural network using the same weights. If the maximum eigenvalue of the matrix is less than 1, gradients will diminish exponentially.
Q6. Does batch normalization fix exploding gradients?
Ans. Batch Normalization mitigates the problem of exploding gradients through ensuring that activations in each layer have zero means and unit variances, thereby constraining the amount by which the signal gets amplified. It does not ensure stability. Exploding gradients may occur if learning rates are high, and BatchNorm does not work well at batch sizes below 4.
Q7. What is a good gradient clipping value?
Ans. The most frequently used default for gradient clipping with the L2 norm is 1.0 in the case of training transformers or large language models. In the training of RNN, the value ranges between 1 to 5. The appropriate value is slightly higher than the usual gradient norm encountered during training, and hence, log norms need to be calculated for a few hundred steps.
Q8. How does LSTM solve the vanishing gradient problem?
Ans. LSTM overcomes the vanishing gradient problem using cell states that update using addition and not matrix multiplication repeatedly. This gradient is regulated using a forget gate, and whenever the forget gate approaches 1, the information persists for many time steps. LSTMs require gradient clipping to handle exploding gradients.
Q9. Do transformers have vanishing gradients?
Ans. Transformer models hardly suffer from vanishing gradients owing to residual connections and normalization, which ensure that gradients flow directly to all layers and the activations are properly scaled. On the other hand, transformer models are still vulnerable to exploding gradients and sharp losses. Post-LN architecture, learning rate warm-up, and normalization up to 1.0 are the common practices.
Final Takeaway
The latent space can be seen as a learned representational space, which acquires meaning from the particular model, training objective, and task used.
For example, the autoencoder uses it as the compressed code. The VAE learns a probabilistic latent space to facilitate generation. GAN uses the latent variables as input to the generator network. A latent diffusion model can implement its generative algorithm in the space of compressed representation. An embedding model learns to embed objects in a vector space for similarity or search purposes. Transformers learn to generate the context-dependent hidden representations of objects; researchers often interpret them as latent space. These are similar concepts, but they are not identical. If there is only one question that you should remember about latent space, then it is the following:
“What representation does the particular model learn, what was its objective during training, and what does the distance or structure in such a representation mean?”
It will give you a much better idea of latent space compared to the general notion of some “internal map in AI.”


